Observability Beyond Logging: Traces, Metrics, and the Missing Context
 Engineering
Logs tell you what happened. Traces tell you why. Here's how to build observability that actually helps you debug production issues fast.
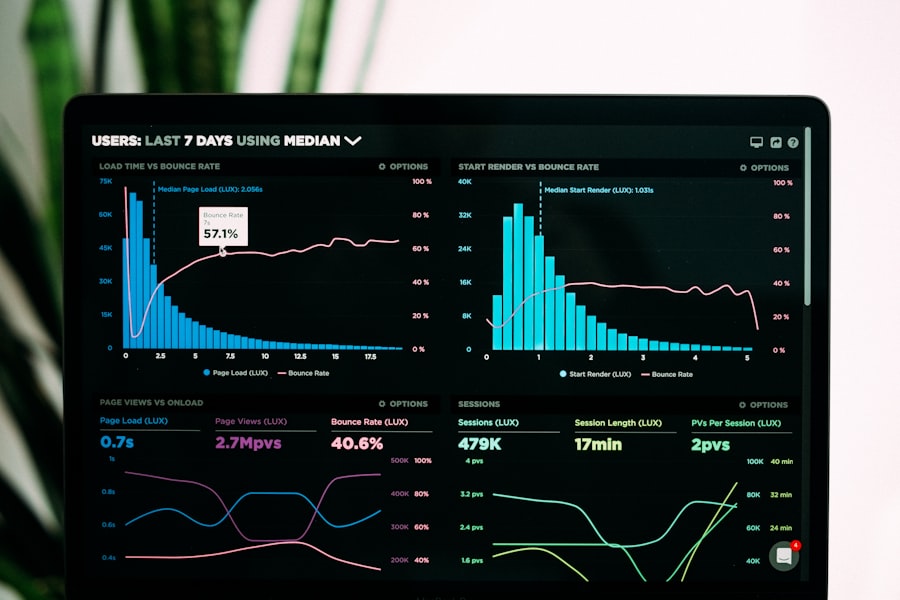
Most teams start with logging and never move beyond it. Logs are useful, but they answer only one question: what happened? When you're debugging a latency spike in a distributed system, you need to know where time was spent - and that requires distributed tracing.
The Three Pillars
- Logs - discrete events with context. Good for errors and audit trails.
- Metrics - aggregated measurements over time. Good for alerting and dashboards.
- Traces - the path of a request across services. Good for debugging latency and failures.
Where to Start
If you're starting from scratch, instrument your most critical user-facing flows first. Add trace context propagation across service boundaries before you worry about sampling rates or storage costs. The most expensive observability investment you can make is the one you skip until after a production incident.
Recent Blogs
View all

The #1 Service Solution
Ready to Transform Your Customer Relationships?
Book a personalised demo with our CRM experts. We'll show you how iZape can be configured for your specific industry, team size, and growth goals - in just 30 minutes.
What to expect:
- Live walkthrough tailored to your use case
- Answers to all your questions from a CRM expert
- Custom pricing based on your team size
- Free 14-day trial after the call
Trusted by 2,500+ Businesses Across India
Request a Free Demo
Fill in your details and we'll be in touch within 24 hours.
By submitting, you agree to our Privacy Policy . No spam, ever.